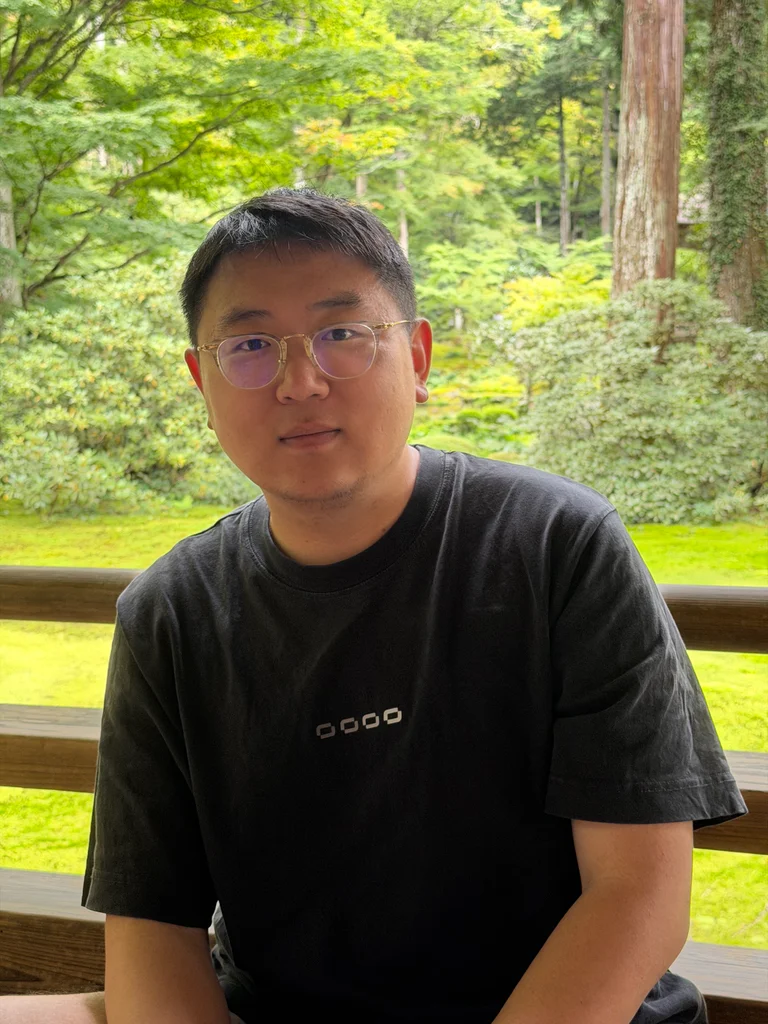
I’m Jiahui Zhang.
I am currently a Ph.D. student at Fudan University, advised by Prof. Li Zhang.
Before joining Fudan, I completed my undergraduate studies at Central South University.
Please feel free to reach out. I would be delighted to connect, exchange ideas, and explore potential collaborations.
More information
- Emailjiahzhang23 (at) m (dot) fudan (dot) edu (dot) cn
- ScholarGoogle Scholar
01
Research
- Open-world Embodied Intelligence
- Robotic Foundation Models
- Robot Data Scaling
My research focuses on building general-purpose robotic systems for the open world. I study how scalable model training and large, diverse robot datasets can enable agents to acquire transferable skills and generalize across tasks, environments, and embodiments.
02
Publications
Learning Transferable Dynamics Priors from Action to World Modeling
Ze Huang*, Jiahui Zhang*, Hairuo Liu, Chenxi Zhang, Ran Cheng, Li Zhang
European Conference on Computer Vision (ECCV), 2026
UniUGG: Unified 3D Understanding and Generation via Geometric-Semantic Encoding
Yueming Xu*, Jiahui Zhang*, Ze Huang*, Yurui Chen, Yanpeng Zhou, Zhenyu Chen, Yu-Jie Yuan, Pengxiang Xia, Guowei Huang, Xinyue Cai, Zhongang Qi, Xingyue Quan, Jianye Hao, Hang Xu, Li Zhang
International Conference on Learning Representations (ICLR), 2026
Reinforcing Action Policies by Prophesying
Jiahui Zhang*, Ze Huang*, Chun Gu, Zipei Ma, Li Zhang
arXiv preprint arXiv:2511.20633, 2025
4D-VLA: Spatiotemporal Vision-Language-Action Pretraining with Cross-Scene Calibration
Jiahui Zhang*, Yurui Chen*, Yueming Xu, Ze Huang, Yanpeng Zhou, Yu-Jie Yuan, Xinyue Cai, Guowei Huang, Xingyue Quan, Hang Xu, Li Zhang
Advances in Neural Information Processing Systems (NeurIPS), 2025
From Flatland to Space: Teaching Vision-Language Models to Perceive and Reason in 3D
Jiahui Zhang*, Yurui Chen*, Yanpeng Zhou, Yueming Xu, Ze Huang, Jilin Mei, Junhui Chen, Yu-Jie Yuan, Xinyue Cai, Guowei Huang, Xingyue Quan, Hang Xu, Li Zhang
Advances in Neural Information Processing Systems (NeurIPS), Datasets and Benchmarks Track, 2025
WoVoGen: World Volume-Aware Diffusion for Controllable Multi-Camera Driving Scene Generation
Jiachen Lu, Ze Huang, Zeyu Yang, Jiahui Zhang, Li Zhang
European Conference on Computer Vision (ECCV), 2024
* Equal contribution.
03
Blogs
Current work: writing the first post. Stay tuned.